 SearchLane
AI Crawlers and robots.txt: Block or Allow? We Analyzed 6 Reddit Threads
Which AI crawlers visit your site, what each does, how to allow AI search but block training in robots.txt, and what 20 people on Reddit decided.
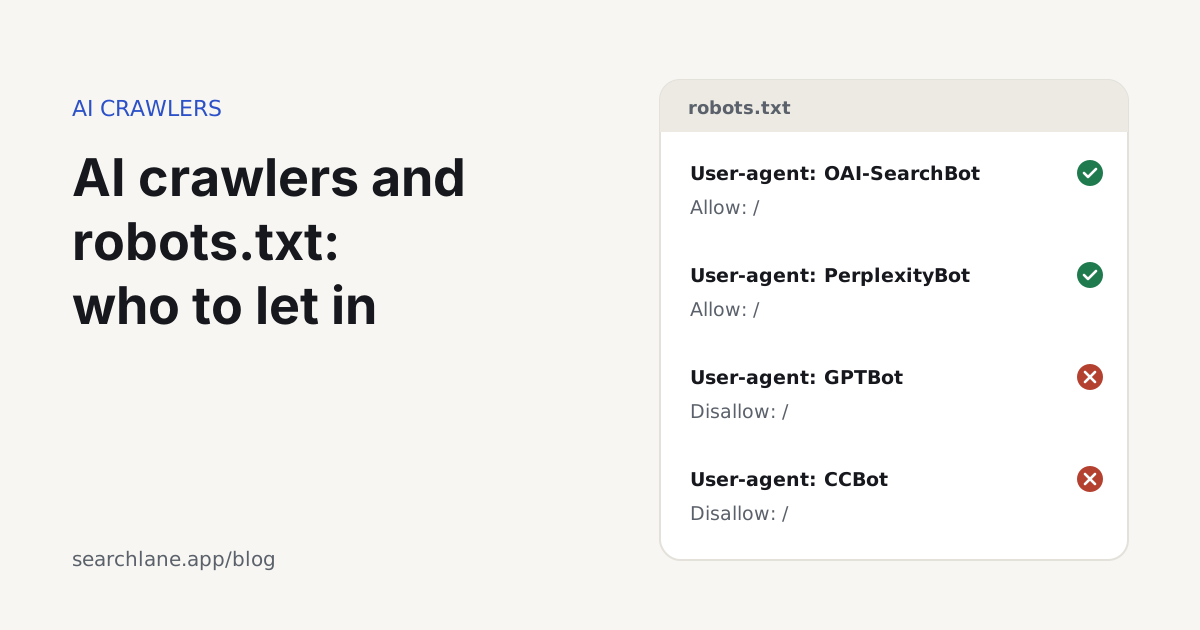
AI companies send different crawlers for different jobs, and robots.txt can treat each one differently. The difference that matters most is between training crawlers, which collect pages to train models, and search crawlers, which fetch pages so an assistant can cite them in an answer. You can block training and still appear in ChatGPT, Claude and Perplexity answers, provided the search crawlers are allowed.
The three kinds of AI crawlers
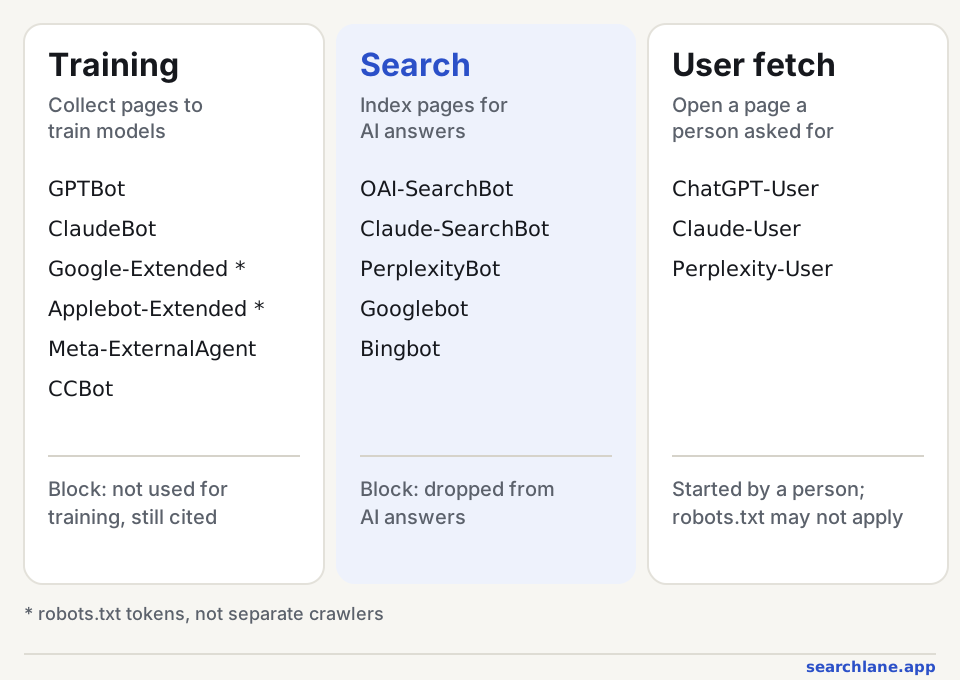
Training crawlers download pages to build datasets for future models. Blocking them doesn't remove you from AI answers today.
Search crawlers build the index an assistant searches when it answers with sources. If you block them, you disappear from those answers.
User-triggered fetchers visit a page because a person asked the assistant to open it. Some vendors say robots.txt may not apply to these, since a human started the visit.
The user agents that matter
| Company | User agent | What it does | Blocking it means |
|---|---|---|---|
| OpenAI | GPTBot | Collects pages for model training | Not used to train future OpenAI models |
| OpenAI | OAI-SearchBot | Indexes pages for ChatGPT search | Not shown or cited in ChatGPT search answers |
| OpenAI | ChatGPT-User | Opens pages when a user asks ChatGPT to | User-initiated; OpenAI notes robots.txt may not apply |
| Anthropic | ClaudeBot | Collects pages for model training | Not used to train Claude |
| Anthropic | Claude-SearchBot | Indexes pages for Claude's search results | Less visible in Claude answers with web search |
| Anthropic | Claude-User | Opens pages when a user asks Claude to | Claude can't fetch your page for that user |
| Perplexity | PerplexityBot | Indexes pages for Perplexity answers (not training) | Not cited in Perplexity answers |
| Perplexity | Perplexity-User | Opens pages when a user asks | User-initiated; Perplexity says it generally ignores robots.txt |
Googlebot | Google Search, including AI Overviews and AI Mode | Out of Google Search entirely | |
Google-Extended | A robots.txt token, not a crawler: controls use of your content for Gemini training and grounding | Doesn't affect Search or AI Overviews | |
| Apple | Applebot-Extended | A token that controls use for Apple's model training | Applebot still crawls for Siri and Spotlight |
| Meta | Meta-ExternalAgent | Collects pages for Meta's AI training | Not used to train Meta's models |
| Common Crawl | CCBot | Open web archive widely used to train models | Out of future Common Crawl snapshots |
| ByteDance | Bytespider | Collects pages for ByteDance's products, reportedly including AI training | Out of its crawl if it obeys robots.txt. Reports say it doesn't always, so many sites also block it at the CDN |
The table follows each vendor's own documentation: OpenAI, Anthropic, Perplexity, Google and Apple. Vendors add and rename bots from time to time, so check those pages before relying on any list, this one included.
Google works differently. There is no separate AI crawler for AI Overviews or AI Mode, which use the normal Googlebot index.
Google-Extendedonly controls Gemini apps and model training. To limit what Google can quote, usenosnippet,max-snippetordata-nosnippeton the page.
Example robots.txt files
Allow AI search, block AI training
Most businesses that want to be cited, but don't want their pages used as training data, end up with something like this:
# AI search and user fetches: allowed
User-agent: OAI-SearchBot
User-agent: ChatGPT-User
User-agent: Claude-SearchBot
User-agent: Claude-User
User-agent: PerplexityBot
User-agent: Perplexity-User
Allow: /

# AI training: blocked
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
User-agent: Applebot-Extended
User-agent: Meta-ExternalAgent
User-agent: CCBot
User-agent: Bytespider
Disallow: /

# Everyone else, including Googlebot and Bingbot
User-agent: *
Allow: /

Sitemap: https://www.example.com/sitemap.xml
Allow everything
If you want the widest possible reach in AI answers and don't mind training use, you don't need any AI-specific rules:
User-agent: *
Allow: /

Sitemap: https://www.example.com/sitemap.xml
Keep a private section out of every bot
User-agent: *
Disallow: /account/
Disallow: /checkout/
robots.txt only asks bots to stay away and doesn't stop anyone from opening a page. Anything private needs a login.
Common mistakes
- Allowing Googlebot and Bingbot and putting a blanket
Disallow: /on everything else. That quietly blocks every AI search crawler too. - Bot protection at the CDN or firewall. It can block AI crawlers even when robots.txt allows them, so check your CDN's AI-bot settings as well.
- Grouping rules wrongly. A crawler follows only the most specific
User-agentgroup that matches it (Google's robots.txt rules explain the matching), so once you nameGPTBotin a group, the rules underUser-agent: *stop applying to it. - Content that only appears after JavaScript runs. Most AI crawlers don't run scripts, so even when they're allowed in, they see an empty page.
- Blocking search crawlers to stop training. Blocking
OAI-SearchBotorPerplexityBotdoes nothing about training and only removes you from answers.
Should you block AI bots? We analyzed 6 Reddit threads
We read six Reddit threads about blocking AI crawlers, from May 2023 to August 2026, in r/SEO, r/TechSEO, r/CloudFlare, r/DigitalMarketing, r/AI_SearchOptimization and r/GEO_optimization: 82 visible comments from 40 people. Twenty of them said what site owners should do:
| Position | People | Share |
|---|---|---|
| Allow them: blocking costs visibility | 7 | 35% |
| Block them: there's no benefit, or they cost bandwidth | 5 | 25% |
| It depends: block training, allow search, decide by business | 4 | 20% |
| robots.txt won't stop them anyway | 4 | 20% |
- The answer depends on how the site makes money. "Most B2B companies and local businesses should want their products included, but publishers, bloggers, illustrators, better to block them" (r/TechSEO). A 2023 reply in r/SEO made the same point with a roofer: when someone asks ChatGPT who should fix a roof in their city, the roofer wants to be named, while a site that lives on ad or affiliate clicks has less to gain.
- Blocking the wrong bot is common. A reply in r/DigitalMarketing found OAI-SearchBot "in the disallow from when I copy-pasted some template two years ago", which kept the site out of ChatGPT search while its owner thought only training was blocked. The same thread pointed out that a CDN setting can block AI crawlers while robots.txt looks clean, and that sending a crawler's user agent from your own computer proves little, because CDNs verify real crawlers by IP address.
- Bandwidth is a real reason to block. A site owner in r/CloudFlare wrote that GPTBot used 30 TB of bandwidth in a month on a 600 MB collection of files, which came to a $150 hosting bill. The host later credited it.
- Experiments need care. In r/GEO_optimization, someone blocked GPTBot on three pages for 30 days and saw ChatGPT citations rise on two of them. Replies pointed out that GPTBot isn't the crawler behind ChatGPT search, that a move from 11 to 14 citations is within normal variation, and that "cutting crawl access mostly stops updates rather than citations".
How we counted
We found the threads through Google (site:reddit.com searches on the topic) and saved them on October 10, 2026, with every visible comment. We counted people, not comments: each person once per thread, by the position they took. We didn't count the thread's author, replies that only asked a question or made a joke, or two replies that promoted a product or service. An AI model sorted the replies into positions, and we checked each label against the reply itself. Removed and deleted comments aren't included. People who answer on Reddit aren't a random sample of site owners, so read the shares as the mood among practitioners, not as a survey.
The threads:
- AI Bots (GPTBot, Perplexity, etc.) - Block All or Allow for Traffic?, r/TechSEO, June 2025
- GPTBot and OAI-SearchBot do different things, and a lot of robots.txt files block the wrong one, r/DigitalMarketing, August 2026
- PSA: check your robots.txt before you block "AI bots " you might be nuking your visibility across half the AI ecosystem by accident, r/AI_SearchOptimization, July 2026
- Do turn on Block AI Bots (or make a robots.txt) if you are hosting something huge on the web, r/CloudFlare, April 2025
- I blocked GPTBot on 3 pages and citations went up on 2 of them — something about GEO doesn't add up, r/GEO_optimization, July 2026
- Is there any reason not to block ChatGPT bot in robots.txt?, r/SEO, May 2023
Our analysis: what the documentation and data say
| What people said | What the documentation or data shows | Verdict |
|---|---|---|
| Blocking GPTBot keeps you out of ChatGPT | OpenAI's docs: GPTBot collects training data, OAI-SearchBot indexes pages for ChatGPT search, and only blocking OAI-SearchBot removes you from search answers | False: they are separate bots |
| robots.txt won't stop them anyway | OpenAI, Anthropic, Google, Apple and Perplexity (for PerplexityBot) say their crawlers follow robots.txt. User-triggered fetchers such as ChatGPT-User and Perplexity-User may not, and some smaller crawlers ignore it | Partly true: it works for the big declared crawlers, not for everyone |
| Blocking GPTBot made citations go up | GPTBot doesn't feed ChatGPT search, the test used three pages without control pages, and pages that are already cited stay in existing indexes | Not supported |
| AI bots can run up your hosting bill | CDNs such as Cloudflare can block or rate-limit AI crawlers at the edge, and caching serves repeat requests without reaching your server | True for large file hosts: block or rate-limit at the CDN |
| Allow them if you're local or B2B, block them if your content is the product | The vendors' own split supports this: search crawlers can bring citations and visits, training crawlers bring neither | Agreed |
What we recommend: allow the AI search crawlers, decide about the training crawlers by whether your content is the product, and check both robots.txt and your CDN settings, since either can block the bots you wanted.
How to check your site
- Open
yourdomain.com/robots.txtand look for the user agents above. - Run the free robots.txt checker. It tests Googlebot and the main AI crawlers against your rules for any page and shows which line decides.
- Check your server or CDN logs for the user agents to confirm they actually reach you.
- Make sure your main pages work without JavaScript. The website audit flags pages whose content only appears after scripts run.
FAQ
Should I block GPTBot?
It depends on whether you mind your content being used to train OpenAI's models. Blocking GPTBot doesn't remove you from ChatGPT search answers, which depend on OAI-SearchBot. Many publishers block GPTBot and allow OAI-SearchBot.
Does blocking Google-Extended remove me from AI Overviews?
No. AI Overviews and AI Mode are part of Google Search and use Googlebot. Google-Extended only controls whether content is used for Gemini apps and model training. Use nosnippet or max-snippet to limit what Google quotes.
Do AI crawlers respect robots.txt?
OpenAI, Anthropic, Google, Apple and Perplexity (for PerplexityBot) say their crawlers follow robots.txt. User-triggered fetchers are a gray area, and some smaller crawlers ignore it. For hard blocking, use your firewall or CDN.
What is llms.txt and does it replace robots.txt?
No. llms.txt is a proposed Markdown file that gives AI tools a short map of your site. It doesn't grant or deny access; robots.txt still controls crawling. What is llms.txt explains the format, and the llms.txt validator checks yours.
What does Reddit say about blocking AI crawlers?
Opinions are split. In six Reddit threads we analyzed, seven of the 20 people who said what to do advised allowing AI crawlers, five advised blocking them, four said it depends on the business or suggested blocking only training bots, and four said robots.txt won't stop them anyway. Local and B2B businesses were usually told to allow them.